The Audience Your Media Plan Calls Targetable Is Sized Against People, But Your Budget Will Be Spent Against Identifiers
People and identifiers are not interchangeable units, and conflating them at the planning stage causes reach estimates and budget assumptions to quietly misalign.
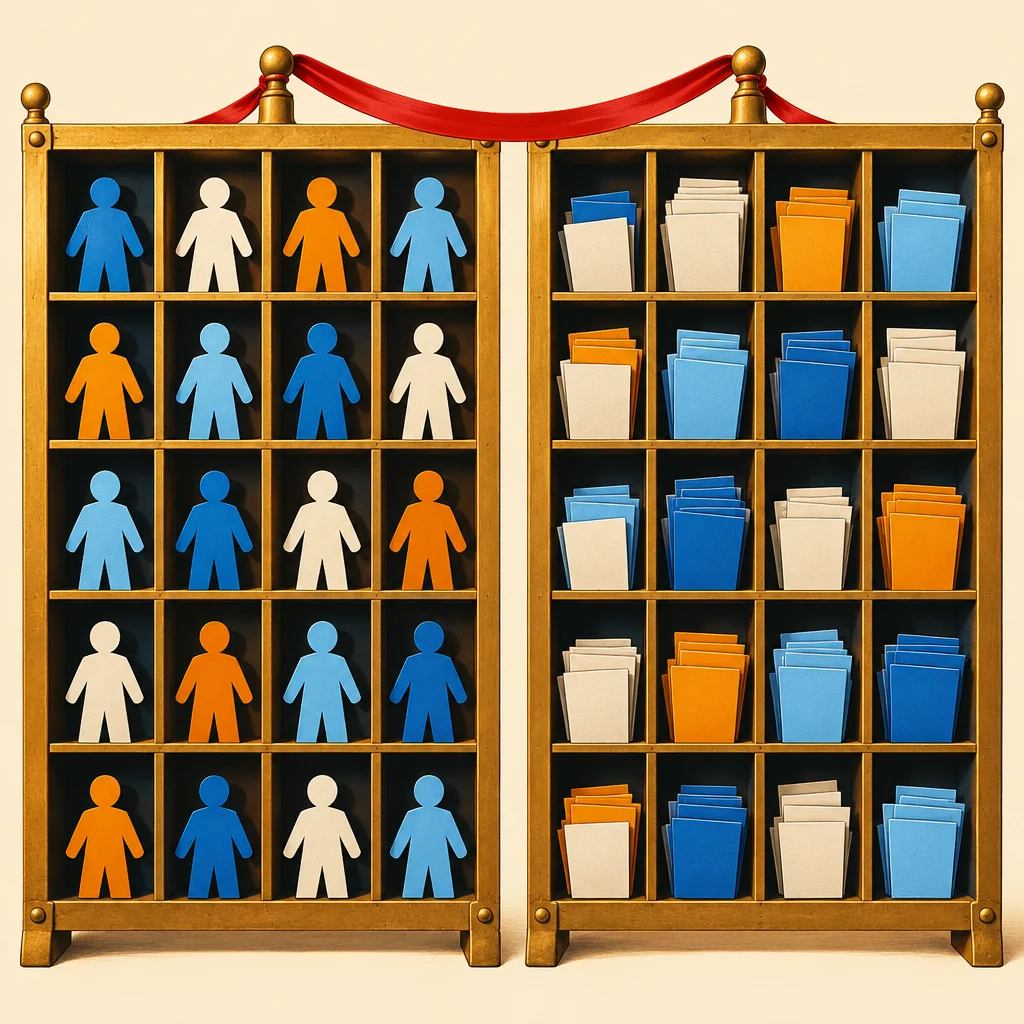
When a media plan lands on a decision-maker's desk, the reach number in the summary row usually reads as a count of people. That framing is intuitive, and it matches how marketers naturally think about audiences. But the systems that actually spend your budget do not operate on people. They operate on identifiers, and a single person can hold several of them simultaneously across devices, browsers, and logged-in environments.
This gap between people and identifiers is not a vendor problem or a data quality failure. It is a structural feature of how programmatic delivery works. Understanding it before a campaign is planned, rather than after results come back looking puzzling, gives buyers a more honest foundation for setting expectations and reading performance data.
What an identifier actually is
An identifier is any token a system can use to recognize a request and decide whether to bid on it. Cookie IDs, mobile advertising IDs, hashed email addresses, IP addresses, and publisher login tokens are all identifiers. None of them is a person. They are signals that a person, or someone using a device, produced at a point in time.
A single person browsing the web in a given week might generate a cookie on their home laptop, a separate mobile ad ID on their phone, a hashed email when they log into a publisher site on a work computer, and a household IP address that covers everyone living with them. From a platform perspective, those can look like four separate audience members. A reach count built from that pool without identity resolution applied will count four, not one.
Why planning tools inherit the problem
Audience sizing tools, whether inside a DSP, a data marketplace, or a planning platform, are typically counting identifiers that match a segment definition, not confirmed unique individuals. The tools are doing exactly what they are built to do. The issue arises when a buyer reads the output as a person count and builds frequency goals, budget allocations, or CPM estimates from that assumption.
If a segment shows 4 million records and you believe those are 4 million people, your plan will assume a certain level of unduplicated reach. If a meaningful share of those records belong to the same people under different identifiers, your actual unduplicated reach is lower, your effective frequency per person is higher than your cap suggests, and your cost-per-unique-reach is higher than the plan projects.
None of this is invisible once you know to look for it. The question is whether you are looking before spend goes out or after.
Where identity resolution fits into this
Identity resolution is the process of grouping identifiers that are believed to belong to the same person. A resolved identity graph collapses those four identifiers from the earlier example into one person-level record. When a segment is built on top of a resolved graph, the reach estimate is closer to an unduplicated person count.
The practical implication for planning is that a segment count from a resolved graph and a segment count from an unresolved identifier pool are not comparable numbers, even if both are labeled as audience size. Asking your vendor or data partner whether their sizing methodology applies identity resolution before counting is a reasonable and specific question that will affect how you interpret the number they give you.
Resolution quality varies. Deterministic resolution, built from confirmed matches like a login event or a purchase record, is generally more reliable but covers fewer people. Probabilistic resolution extends coverage by inferring connections, but introduces some rate of error. A segment sized on a probabilistic graph may look larger while containing more identifier groupings that do not map cleanly to single individuals. Neither approach is wrong, but they produce numbers that mean different things.
Frequency caps and the person-versus-identifier gap
One area where this distinction becomes operationally consequential is frequency management. A frequency cap set at the campaign or line-item level governs how many times a given identifier is served, not how many times a given person is served. If a person holds three active identifiers that are not resolved together, they can receive three times your intended cap exposure without any individual identifier exceeding its limit.
For brand advertisers concerned about creative wear, this matters because actual exposure is higher than the plan suggests. For direct response buyers focused on conversion efficiency, serving the same person repeatedly under different identifiers consumes budget that could have reached genuinely new audience members.
Some DSPs offer people-based frequency management when powered by a resolved identity graph, but this feature depends on the quality and coverage of that graph. Asking specifically how a platform enforces frequency at the person level, rather than the identifier level, is a useful scoping question before a campaign launches.
Reading post-campaign reach reports with this in mind
Post-campaign reports typically surface reach in terms of unique identifiers served unless the platform or vendor explicitly states otherwise. A reach report showing 2 million unique users is usually showing 2 million unique identifier instances. The number of unique people those represent depends on the resolution layer applied, if any.
When comparing reach across campaigns or vendors, treating identifier counts as comparable person counts can produce misleading conclusions. A campaign that ran against a resolved audience may show lower raw reach numbers while actually touching more unique individuals than a campaign that ran against a larger but unresolved pool.
A simple habit that helps: when a reach number surfaces in any report or proposal, ask one clarifying question. Is this count at the identifier level or has identity resolution been applied to estimate unique people? The answer shapes how you read everything downstream from that number.
A planning posture that accounts for this
None of this requires a buyer to become an identity graph expert. It does require treating reach estimates as estimates with methodological assumptions behind them rather than as objective counts.
When building a media plan, it is reasonable to build in a conservative assumption that raw identifier reach will be somewhat larger than resolved person reach, and that effective frequency per person will run somewhat higher than the identifier-level cap implies. The size of that adjustment depends on how much identity resolution your supply path applies, which is a detail worth surfacing with your data or platform partners before the brief is finalized rather than after results return.
The goal is not to distrust the numbers. It is to read them for what they actually measure, so that the planning assumptions and the delivery mechanics are working from the same definition of audience.